0

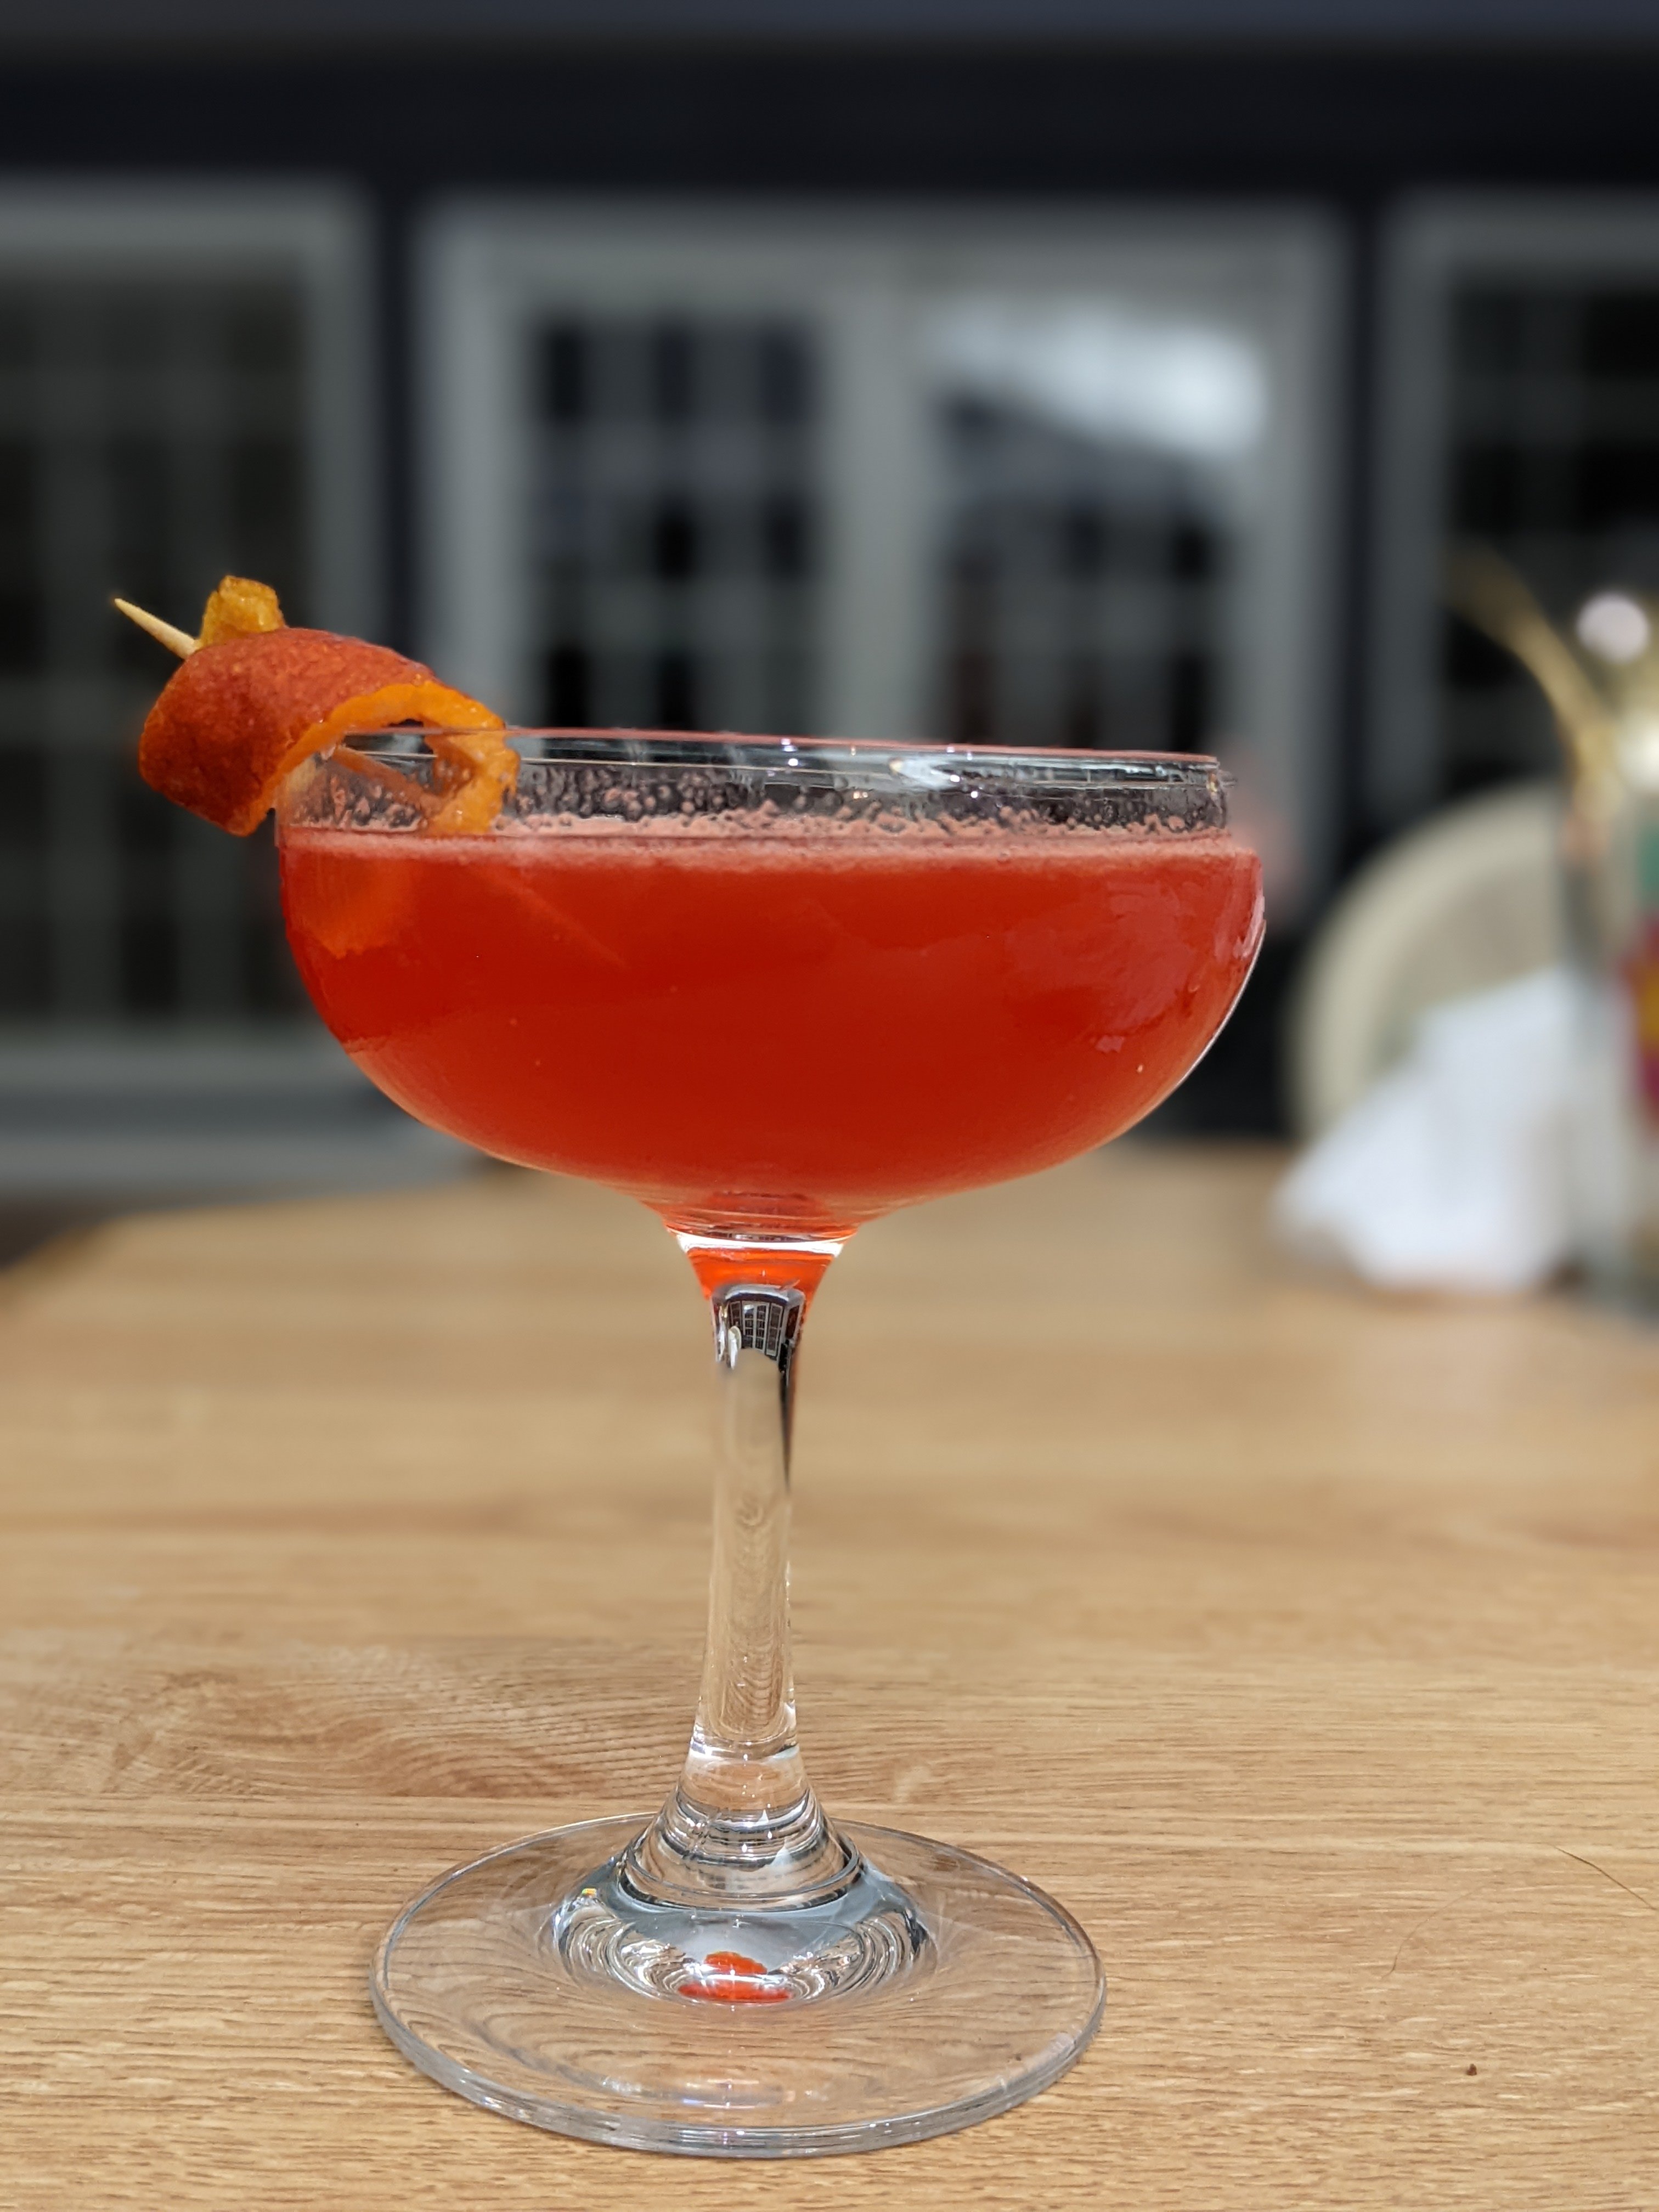
Daiquiri - Plantaray XO

preview
  • ½ fl oz Real Lime juice
  • ½ fl oz Volcano lime juice
  • ½ fl oz 2:1 cane sugar simple
  • 1 ½ fl oz Plantaray XO

Dehydrated lime wheel garnish

When I make these for others I ask 2 questions: how sweet and do you want the lime snappy Sweet obv. varies the simple & snappy lime requests get a pinch of mallic acid in the shaker and a smidge more real lime than volcano

  • ½ fl oz Real Lime juice
  • ½ fl oz Volcano lime juice
  • ½ fl oz 2:1 cane sugar simple
  • 1 ½ fl oz Plantaray XO

Dehydrated lime wheel garnish

When I make these for others I ask 2 questions: how sweet and do you want the lime snappy Sweet obv. varies the simple & snappy lime requests get a pinch of mallic acid in the shaker and a smidge more real lime than volcano

0

Daily bunny no.3496 has been framed!

preview

A bunny in the entryway of a suburban home witnesses a smashed flowerpot on the clean floor, with a look of shock on their face. On the drawer the flowerpot was on, a smug black cat is seated. There is a picture of the cat on the wall

Source: Bluesky

A bunny in the entryway of a suburban home witnesses a smashed flowerpot on the clean floor, with a look of shock on their face. On the drawer the flowerpot was on, a smug black cat is seated. There is a picture of the cat on the wall

Source: Bluesky

0

TV tonight: Stacey Dooley takes an Australian adventure with a twist

the Guardian TV tonight: Stacey Dooley takes an Australian adventure with a twist www.theguardian.com
preview

The star goes off the beaten track to visit neglected parts. Plus, more oceanic wonder in Blue Planet III. Here’s what to watch this evening

9pm, Channel 4

Continue reading…

The star goes off the beaten track to visit neglected parts. Plus, more oceanic wonder in Blue Planet III. Here’s what to watch this evening

9pm, Channel 4

Continue reading…

0

Any people who have played open-source Minecraft alternatives?

preview

cross-posted from: reddthat.com/post/76256590

I’ve tried to do research and found games that exist, but not many opinions on them. I don’t wanna rely on one singular opinion just to find out that the game is for them but not me. Classicube ie too simple. Cubys is like Minecraft’s Arch, and Luanti with Mineclonia seems the most promising, but have done the least research from. Eaglercraft isn’t fully open-source liscense-wize, Android java launchers like Mojo use too many resources, and PC launchers require a Minecraft install and a Microsoft account. I don’t wanna just straight up pirate the game directly either. How are your experiences woth those complete alternatives?

cross-posted from: reddthat.com/post/76256590

I’ve tried to do research and found games that exist, but not many opinions on them. I don’t wanna rely on one singular opinion just to find out that the game is for them but not me. Classicube ie too simple. Cubys is like Minecraft’s Arch, and Luanti with Mineclonia seems the most promising, but have done the least research from. Eaglercraft isn’t fully open-source liscense-wize, Android java launchers like Mojo use too many resources, and PC launchers require a Minecraft install and a Microsoft account. I don’t wanna just straight up pirate the game directly either. How are your experiences woth those complete alternatives?

0

How would you solve the overhang?

preview

The election results this year are bad. Even if you voted for the national coalition, I think you should be angry about this year’s results because they go against the point of MMP. I have two ideas of how to fix overhangs and make sure the government is always proportional, but I’d love to hear your thoughts on it.

Idea 1, the simpler solution: Just add more list seats. Fill up all the electorate seats, then add list MPs until there are at least the base number of seats, and adding another seat would make it less proportional. Pros: It’s simple, intuitive, and makes more sense than allowing overhangs. Cons: There could be a lot of MPs in the house.

Idea 2, STV + MMP: This idea uses STV or some other ranked system to elect the electorate MPs, which would be better than the FPTP we use for them now. But in this case, if an overhang happens, the overhang seat with the thinnest majority would be recalculated with the previous winner’s votes transferred. Pros: it works in a better system for the electorates, and it makes for a consistent size of parliament. Cons: It’s slightly more confusing for the voters, and calculating the seats could take much longer.

The election results this year are bad. Even if you voted for the national coalition, I think you should be angry about this year’s results because they go against the point of MMP. I have two ideas of how to fix overhangs and make sure the government is always proportional, but I’d love to hear your thoughts on it.

Idea 1, the simpler solution: Just add more list seats. Fill up all the electorate seats, then add list MPs until there are at least the base number of seats, and adding another seat would make it less proportional. Pros: It’s simple, intuitive, and makes more sense than allowing overhangs. Cons: There could be a lot of MPs in the house.

Idea 2, STV + MMP: This idea uses STV or some other ranked system to elect the electorate MPs, which would be better than the FPTP we use for them now. But in this case, if an overhang happens, the overhang seat with the thinnest majority would be recalculated with the previous winner’s votes transferred. Pros: it works in a better system for the electorates, and it makes for a consistent size of parliament. Cons: It’s slightly more confusing for the voters, and calculating the seats could take much longer.

-1

Normals has a Showcase section for your games, with feedback

preview

Hey! This is coming from normals.me, the forum that mirrors this community. Quick thing for the people here who make games, especially browser and small indie stuff.

Normals has a section called Showcase, https://normals.me/showcase, where you post your own project and that's allowed by design. Your post gets a "own product" label, there's one promo per product per community with a cooldown you see up front, and that's it. No guessing whether a mod will nuke it, no pretending to be a random fan. Say it's yours, link it, get feedback.

Why I'm posting it here, last week someone posted about a small card game in this community and got called a bot for three comments before people realized he was just a fan. That whole mess happens because most places have no honest way to say "I made this" or "I like this". Showcase is that way. You can reply to Showcase posts from your own instance too, it all federates.

#indiehackers #indiedev #gaming #gamedev

https://normals.me/showcase

Hey! This is coming from normals.me, the forum that mirrors this community. Quick thing for the people here who make games, especially browser and small indie stuff.

Normals has a section called Showcase, https://normals.me/showcase, where you post your own project and that's allowed by design. Your post gets a "own product" label, there's one promo per product per community with a cooldown you see up front, and that's it. No guessing whether a mod will nuke it, no pretending to be a random fan. Say it's yours, link it, get feedback.

Why I'm posting it here, last week someone posted about a small card game in this community and got called a bot for three comments before people realized he was just a fan. That whole mess happens because most places have no honest way to say "I made this" or "I like this". Showcase is that way. You can reply to Showcase posts from your own instance too, it all federates.

#indiehackers #indiedev #gaming #gamedev

https://normals.me/showcase

0

How to passively stop or slow friends and family wasting hours daily scrolling or consuming content.

preview

I see friends, family, strangers, subconsciously go for their phones during thoughtless times daily. Have a moment to think… Scroll. Showering with their phone propped up watching a video. First wake up and spend an hour or two frying the mind.

It has gotten so bad in my friend group and close family I swear they could not function emotionally without consuming content. When you bring it up or any negative about it. Anger, distasteful emotions. How do you talk, convince, gain real traction towards slowing or decreasing time spent. Once or twice a day could be ok. These people do it for sometimes hours daily. It’s sickening. Advice?

I see friends, family, strangers, subconsciously go for their phones during thoughtless times daily. Have a moment to think… Scroll. Showering with their phone propped up watching a video. First wake up and spend an hour or two frying the mind.

It has gotten so bad in my friend group and close family I swear they could not function emotionally without consuming content. When you bring it up or any negative about it. Anger, distasteful emotions. How do you talk, convince, gain real traction towards slowing or decreasing time spent. Once or twice a day could be ok. These people do it for sometimes hours daily. It’s sickening. Advice?

0

[Fil Quotidien] Jeux de mot et plus du jour; le 08/11

preview

**Jeux de mots **

sutom.nocle.fr

cemantix.certitudes.org

pedantix.certitudes.org

www.portail-lexical.fr/jeux

Divers

accura.city (Géograhpie)

www.eggnog.ai/entertimeportal (Histoire)

retrotrivia.games (Culture jeux vidéos)

cluesbysam.com (enquête)

metazooa.com (Animaux)

realitycheckk.com (AI ou humains ?)

**Jeux de mots **

sutom.nocle.fr

cemantix.certitudes.org

pedantix.certitudes.org

www.portail-lexical.fr/jeux

Divers

accura.city (Géograhpie)

www.eggnog.ai/entertimeportal (Histoire)

retrotrivia.games (Culture jeux vidéos)

cluesbysam.com (enquête)

metazooa.com (Animaux)

realitycheckk.com (AI ou humains ?)

0

PR merged: llama_moe_cache: run missed experts on CPU - Tested on 32GB RAM and 8GB VRAM with Tiel 35b, Gemma 26b, and LFM 24b

GitHub llama_moe_cache: run missed experts on CPU, add tuning script by am17an · Pull Request #30966 · ggml-org/llama.cpp github.com
preview

am17an: Before you guys bash llama.cpp again - I know it’s not there yet. I’m working on it.

am17an: I’m working towards an “auto” mode here, thinking about a good UX.

I tried this on my Ryzen 2600, 32GB DDR4 RAM, RTX 2080 8GB, PCIe 3 desktop. The tuning script takes about 5 minutes to run but it gives you recommended settings. I tested Tiel 35b, Gemma 26b, and LFM 2.5 24b, all without mmproj (or with --no-mmproj-offload). If you have PCIe 5, your numbers will probably look different even with the same 8GB VRAM.

My real world numbers seem about 20% slower than what the tune script is predicting, but still I’m getting the fastest speeds I’ve ever seen in llama.cpp on my computer, and I’ve tried a few of these different attempts at MoE caching.

Tiel 35b

$ python3 scripts/moe-cache-tune.py -- build/bin/llama-server -m ~/Documents/LLMs/Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf -cmoe -c 77824 --cache-type-k q8_0 --cache-type-v q8_0

1/6 1856 MiB, share 0: 35.3 t/s
2/6 1856 MiB, share 0.5: 38.6 t/s
3/6 1856 MiB, share 0.95: 50.1 t/s
4/6 3136 MiB, share 0: 41.1 t/s
5/6 3136 MiB, share 0.5: 47.3 t/s
6/6 3136 MiB, share 0.95: 53.5 t/s

[The script pauses here for a few minutes...]

Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf: 18760 MiB of experts, CUDA0 7284 MiB free, cache up to 3188 MiB

  cache MiB  share   t/s  hits
       1856      0  35.3   73%
       1856    0.5  38.6   66%
       1856   0.95  50.1   64%
       3136      0  41.1   81%
       3136    0.5  47.3   79%
       3136   0.95  53.5   73%

machine: uploads 10.9 GiB/s, CPU 40.8 GiB/s, CPU part 0.00 ms, overlap 1.4 ms/GiB, rest 14.14 ms per token, fit within 0.7%

predicted t/s, warm cache:
  cache MiB     0   0.5   0.8   0.9  0.95  0.98
        896  25.3  32.8  39.6  42.4  43.9  44.6
       1856  32.8  39.8  46.3  48.8  49.9  50.3
       3136  41.6  47.7  52.9  54.7  55.4  55.4

recommended: --moe-cache-mib 3136 --moe-cache-cpu-share 0.8 (52.9 t/s, 41.6 with share 0)

Interesting to note that 1856MB and 0.95 share is almost as fast as 3136MB and 0.8 share. This means it might be worth reducing the cache size in order to use MTP, or maybe I should start using a higher quant.

But looking at the “predicted” table, it seems like the fastest would actually be 3136 MB and 0.98 share for 55.4 tok/sec? Not sure why it doesn’t recommend that instead, maybe it’s an expected peak not average.

Forcing Lower VRAM Usage

You can use –max-mib to force it to tune your settings with a lower VRAM usage, just make sure you put this argument before the llama-server portion of the arguments. It seems to work in steps, so not every number is respected, and the initial data collection run still seems able to use more than your requested amount, but the recommendation will respect it.

$ python3 scripts/moe-cache-tune.py --max-mib 2500 -- build/bin/llama-server -m ~/Documents/LLMs/Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf -cmoe -c 77824 --cache-type-k q8_0 --cache-type-v q8_0

1/6 1856 MiB, share 0: 34.1 t/s
2/6 1856 MiB, share 0.5: 37.4 t/s
3/6 1856 MiB, share 0.95: 49.8 t/s
4/6 3136 MiB, share 0: 41.6 t/s
5/6 3136 MiB, share 0.5: 44.9 t/s
6/6 3136 MiB, share 0.95: 54.1 t/s
Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf: 18760 MiB of experts, CUDA0 7292 MiB free, cache up to 2500 MiB

  cache MiB  share   t/s  hits
       1856      0  34.1   73%
       1856    0.5  37.4   66%
       1856   0.95  49.8   64%
       3136      0  41.6   81%
       3136    0.5  44.9   79%
       3136   0.95  54.1   73%

machine: uploads 8.7 GiB/s, CPU 47.0 GiB/s, CPU part 3.06 ms, overlap -12.2 ms/GiB, rest 11.50 ms per token, fit within 1.3%

predicted t/s, warm cache:
  cache MiB     0   0.5   0.8   0.9  0.95  0.98
        896  23.2  31.6  39.4  42.8  44.7  45.7
       1856  31.4  38.3  45.7  48.8  50.3  50.9
       2496  36.9  42.5  49.1  51.8  53.0  53.4

recommended: --moe-cache-mib 2496 --moe-cache-cpu-share 0.9 (51.8 t/s, 36.9 with share 0)

It recommended a slightly higher “share” meaning it allows more to run on the CPU, to reduce movement of data.

Testing with GPU Power Limit

I used sudo nvidia-smi -pl 125 to limit my GPU’s power from 225 down to 125:

$ python3 scripts/moe-cache-tune.py -- build/bin/llama-server -m ~/Documents/LLMs/Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf -cmoe -c 77824 --cache-type-k q8_0 --cache-type-v q8_0

1/6 1856 MiB, share 0: 29.5 t/s
2/6 1856 MiB, share 0.5: 38.6 t/s
3/6 1856 MiB, share 0.95: 48.9 t/s
4/6 3136 MiB, share 0: 41.4 t/s
5/6 3136 MiB, share 0.5: 46.8 t/s
6/6 3136 MiB, share 0.95: 52.1 t/s
Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf: 18760 MiB of experts, CUDA0 7288 MiB free, cache up to 3192 MiB

  cache MiB  share   t/s  hits
       1856      0  29.5   73%
       1856    0.5  38.6   66%
       1856   0.95  48.9   64%
       3136      0  41.4   81%
       3136    0.5  46.8   79%
       3136   0.95  52.1   73%

machine: uploads 7.6 GiB/s, CPU 26.4 GiB/s, CPU part 0.00 ms, overlap 0.0 ms/GiB, rest 11.30 ms per token, fit within 7.9%

predicted t/s, warm cache:
  cache MiB     0   0.5   0.8   0.9  0.95  0.98
        896  21.1  28.8  36.1  39.3  41.0  41.7
       1856  29.0  37.0  44.9  48.0  49.4  49.8
       3136  39.4  47.5  54.6  57.2  58.1  57.8

recommended: --moe-cache-mib 3136 --moe-cache-cpu-share 0.9 (57.2 t/s, 39.4 with share 0)

You can see GPU power limits don’t affect token generation much, it has a bigger impact on prefill speed. The cpu share is a little higher because the power limit makes the expert movement slightly less valueable. The predictions seem a bit… unpredictable. This run had slightly slower figures for every test, but ended up predicting a higher speed, who knows why.

Gemma 4 26b

With Gemma 4 26b QAT I got:

recommended: --moe-cache-mib 3328 --moe-cache-cpu-share 0.8 (50.1 t/s, 40.3 with share 0)

And with 131072 context:

recommended: --moe-cache-mib 2496 --moe-cache-cpu-share 0.9 (45.7 t/s, 30.5 with share 0)

LFM 2.5 24b

With LFM 2.5 24b QAD I got:

recommended: --moe-cache-mib 5056 --moe-cache-cpu-share 0.9 (75.7 t/s, 51.5 with share 0)

I wonder why this one suggested a high share when the cache size nearly half of the model size. Maybe it’s because the experts that aren’t cached are infrequently used. So when your cache is big enough to hold every frequently used expert, they aren’t worth moving back and forth.
am17an: Before you guys bash llama.cpp again - I know it’s not there yet. I’m working on it.

am17an: I’m working towards an “auto” mode here, thinking about a good UX.

I tried this on my Ryzen 2600, 32GB DDR4 RAM, RTX 2080 8GB, PCIe 3 desktop. The tuning script takes about 5 minutes to run but it gives you recommended settings. I tested Tiel 35b, Gemma 26b, and LFM 2.5 24b, all without mmproj (or with --no-mmproj-offload). If you have PCIe 5, your numbers will probably look different even with the same 8GB VRAM.

My real world numbers seem about 20% slower than what the tune script is predicting, but still I’m getting the fastest speeds I’ve ever seen in llama.cpp on my computer, and I’ve tried a few of these different attempts at MoE caching.

Tiel 35b

$ python3 scripts/moe-cache-tune.py -- build/bin/llama-server -m ~/Documents/LLMs/Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf -cmoe -c 77824 --cache-type-k q8_0 --cache-type-v q8_0

1/6 1856 MiB, share 0: 35.3 t/s
2/6 1856 MiB, share 0.5: 38.6 t/s
3/6 1856 MiB, share 0.95: 50.1 t/s
4/6 3136 MiB, share 0: 41.1 t/s
5/6 3136 MiB, share 0.5: 47.3 t/s
6/6 3136 MiB, share 0.95: 53.5 t/s

[The script pauses here for a few minutes...]

Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf: 18760 MiB of experts, CUDA0 7284 MiB free, cache up to 3188 MiB

  cache MiB  share   t/s  hits
       1856      0  35.3   73%
       1856    0.5  38.6   66%
       1856   0.95  50.1   64%
       3136      0  41.1   81%
       3136    0.5  47.3   79%
       3136   0.95  53.5   73%

machine: uploads 10.9 GiB/s, CPU 40.8 GiB/s, CPU part 0.00 ms, overlap 1.4 ms/GiB, rest 14.14 ms per token, fit within 0.7%

predicted t/s, warm cache:
  cache MiB     0   0.5   0.8   0.9  0.95  0.98
        896  25.3  32.8  39.6  42.4  43.9  44.6
       1856  32.8  39.8  46.3  48.8  49.9  50.3
       3136  41.6  47.7  52.9  54.7  55.4  55.4

recommended: --moe-cache-mib 3136 --moe-cache-cpu-share 0.8 (52.9 t/s, 41.6 with share 0)

Interesting to note that 1856MB and 0.95 share is almost as fast as 3136MB and 0.8 share. This means it might be worth reducing the cache size in order to use MTP, or maybe I should start using a higher quant.

But looking at the “predicted” table, it seems like the fastest would actually be 3136 MB and 0.98 share for 55.4 tok/sec? Not sure why it doesn’t recommend that instead, maybe it’s an expected peak not average.

Forcing Lower VRAM Usage

You can use –max-mib to force it to tune your settings with a lower VRAM usage, just make sure you put this argument before the llama-server portion of the arguments. It seems to work in steps, so not every number is respected, and the initial data collection run still seems able to use more than your requested amount, but the recommendation will respect it.

$ python3 scripts/moe-cache-tune.py --max-mib 2500 -- build/bin/llama-server -m ~/Documents/LLMs/Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf -cmoe -c 77824 --cache-type-k q8_0 --cache-type-v q8_0

1/6 1856 MiB, share 0: 34.1 t/s
2/6 1856 MiB, share 0.5: 37.4 t/s
3/6 1856 MiB, share 0.95: 49.8 t/s
4/6 3136 MiB, share 0: 41.6 t/s
5/6 3136 MiB, share 0.5: 44.9 t/s
6/6 3136 MiB, share 0.95: 54.1 t/s
Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf: 18760 MiB of experts, CUDA0 7292 MiB free, cache up to 2500 MiB

  cache MiB  share   t/s  hits
       1856      0  34.1   73%
       1856    0.5  37.4   66%
       1856   0.95  49.8   64%
       3136      0  41.6   81%
       3136    0.5  44.9   79%
       3136   0.95  54.1   73%

machine: uploads 8.7 GiB/s, CPU 47.0 GiB/s, CPU part 3.06 ms, overlap -12.2 ms/GiB, rest 11.50 ms per token, fit within 1.3%

predicted t/s, warm cache:
  cache MiB     0   0.5   0.8   0.9  0.95  0.98
        896  23.2  31.6  39.4  42.8  44.7  45.7
       1856  31.4  38.3  45.7  48.8  50.3  50.9
       2496  36.9  42.5  49.1  51.8  53.0  53.4

recommended: --moe-cache-mib 2496 --moe-cache-cpu-share 0.9 (51.8 t/s, 36.9 with share 0)

It recommended a slightly higher “share” meaning it allows more to run on the CPU, to reduce movement of data.

Testing with GPU Power Limit

I used sudo nvidia-smi -pl 125 to limit my GPU’s power from 225 down to 125:

$ python3 scripts/moe-cache-tune.py -- build/bin/llama-server -m ~/Documents/LLMs/Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf -cmoe -c 77824 --cache-type-k q8_0 --cache-type-v q8_0

1/6 1856 MiB, share 0: 29.5 t/s
2/6 1856 MiB, share 0.5: 38.6 t/s
3/6 1856 MiB, share 0.95: 48.9 t/s
4/6 3136 MiB, share 0: 41.4 t/s
5/6 3136 MiB, share 0.5: 46.8 t/s
6/6 3136 MiB, share 0.95: 52.1 t/s
Tiel-Coder-35B-A3B-UD-Q4_K_XL.gguf: 18760 MiB of experts, CUDA0 7288 MiB free, cache up to 3192 MiB

  cache MiB  share   t/s  hits
       1856      0  29.5   73%
       1856    0.5  38.6   66%
       1856   0.95  48.9   64%
       3136      0  41.4   81%
       3136    0.5  46.8   79%
       3136   0.95  52.1   73%

machine: uploads 7.6 GiB/s, CPU 26.4 GiB/s, CPU part 0.00 ms, overlap 0.0 ms/GiB, rest 11.30 ms per token, fit within 7.9%

predicted t/s, warm cache:
  cache MiB     0   0.5   0.8   0.9  0.95  0.98
        896  21.1  28.8  36.1  39.3  41.0  41.7
       1856  29.0  37.0  44.9  48.0  49.4  49.8
       3136  39.4  47.5  54.6  57.2  58.1  57.8

recommended: --moe-cache-mib 3136 --moe-cache-cpu-share 0.9 (57.2 t/s, 39.4 with share 0)

You can see GPU power limits don’t affect token generation much, it has a bigger impact on prefill speed. The cpu share is a little higher because the power limit makes the expert movement slightly less valueable. The predictions seem a bit… unpredictable. This run had slightly slower figures for every test, but ended up predicting a higher speed, who knows why.

Gemma 4 26b

With Gemma 4 26b QAT I got:

recommended: --moe-cache-mib 3328 --moe-cache-cpu-share 0.8 (50.1 t/s, 40.3 with share 0)

And with 131072 context:

recommended: --moe-cache-mib 2496 --moe-cache-cpu-share 0.9 (45.7 t/s, 30.5 with share 0)

LFM 2.5 24b

With LFM 2.5 24b QAD I got:

recommended: --moe-cache-mib 5056 --moe-cache-cpu-share 0.9 (75.7 t/s, 51.5 with share 0)

I wonder why this one suggested a high share when the cache size nearly half of the model size. Maybe it’s because the experts that aren’t cached are infrequently used. So when your cache is big enough to hold every frequently used expert, they aren’t worth moving back and forth.
7

There was a Cute Girl in the Hero's Party, so I Tried Confessing to Her | Season 2 Announced

https://yuukawa-anime.com TVアニメ『勇者パーティーにかわいい⼦がいたので、告⽩してみた。』 第2期制作決定! | News | TVアニメ『勇者パーティにかわいい子がいたので、告白してみた。』公式サイト yuukawa-anime.com
0

What are some timeless movies that still hold up today?

preview

What are some movies that are still amazing, even if you watch it now? Think movies that don’t have sexist or similarly awful jokes that have aged poorly, with special effects that are still wonderful, and characters you can still relate with. Movies old and new are equally awesome :D

What are some movies that are still amazing, even if you watch it now? Think movies that don’t have sexist or similarly awful jokes that have aged poorly, with special effects that are still wonderful, and characters you can still relate with. Movies old and new are equally awesome :D
0

New Orleans General Strike (1892) On this day in 1892, a general strike across racial lines broke out in New Orleans, a city-wide action of solidarity with three unions on strike

preview

New Orleans General Strike (1892)

Tue Nov 08, 1892

Image

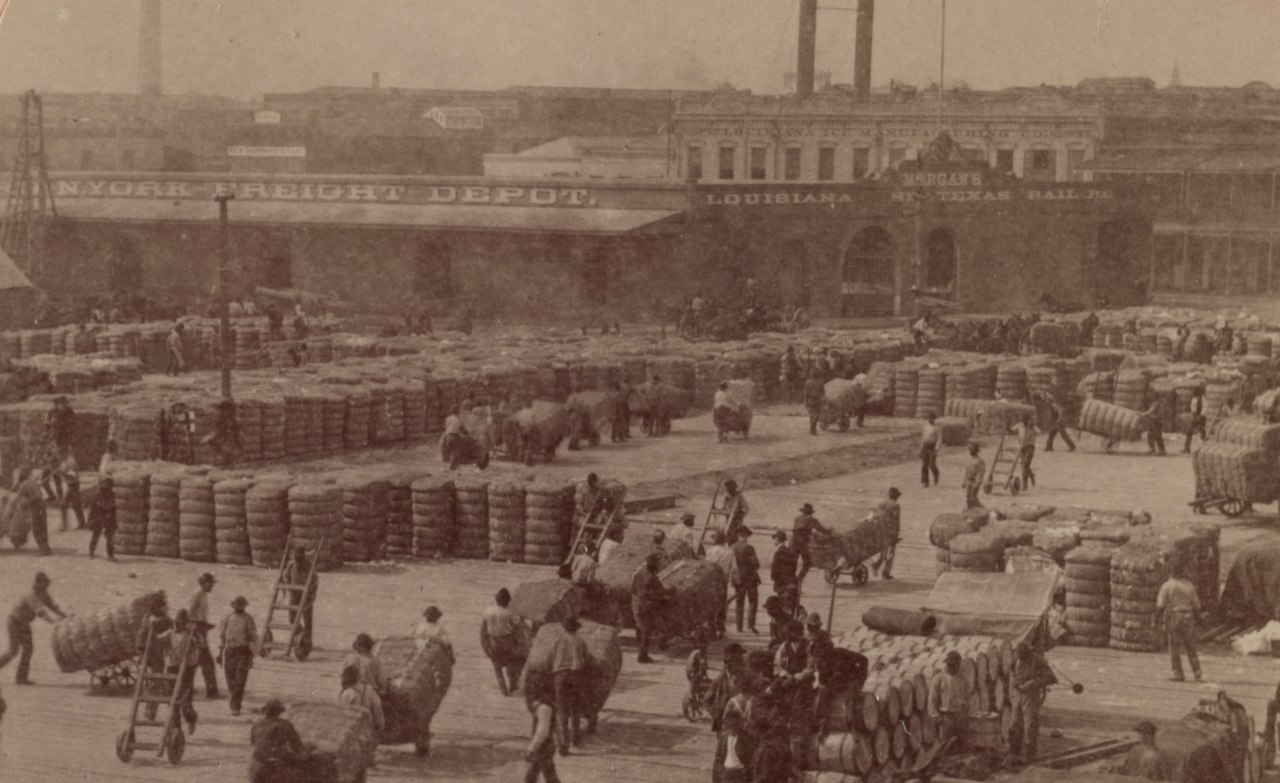
Image: Photograph of tracking cotton from steamboat taken in 1891 in New Orleans, Levee. Photo shows dockworkers moving cotton from steamboat to the distribution area.

On this day in 1892, a general strike across racial lines broke out in New Orleans, a city-wide action of solidarity with three unions on strike. After white workers refused racial bribes, workers won their demands in just three days.

The general strike grew out of a strike by three unions who had joined forces to go on strike the two weeks prior. The three unions, collectively known as the “Triple Alliance”, were an alliance of black and white workers. The New Orleans Board of Trade announced it would sign contracts agreeing to the terms - but only with the white unions, however this offer was steadfastly refused.

Eventually, other union leaders in the city began calling for a strike in support of the Triple Alliance, and, on this day in 1892, a multi-racial coalition of 25,000 workers across the entire city went on strike. Efforts by the city to find strikebreaking workers, both from within and outside of New Orleans, failed.

After just three days, the Board of Trade agreed to binding arbitration to settle the strike, with employers agreeing to sit down with both white and black union leaders. After 48 hours of negotiations, the employers agreed to the 10-hour day and overtime pay for the Triple Alliance workers. Members of other unions also won reduced hours and higher pay.


New Orleans General Strike (1892)

Tue Nov 08, 1892

Image

Image: Photograph of tracking cotton from steamboat taken in 1891 in New Orleans, Levee. Photo shows dockworkers moving cotton from steamboat to the distribution area.


On this day in 1892, a general strike across racial lines broke out in New Orleans, a city-wide action of solidarity with three unions on strike. After white workers refused racial bribes, workers won their demands in just three days.

The general strike grew out of a strike by three unions who had joined forces to go on strike the two weeks prior. The three unions, collectively known as the “Triple Alliance”, were an alliance of black and white workers. The New Orleans Board of Trade announced it would sign contracts agreeing to the terms - but only with the white unions, however this offer was steadfastly refused.

Eventually, other union leaders in the city began calling for a strike in support of the Triple Alliance, and, on this day in 1892, a multi-racial coalition of 25,000 workers across the entire city went on strike. Efforts by the city to find strikebreaking workers, both from within and outside of New Orleans, failed.

After just three days, the Board of Trade agreed to binding arbitration to settle the strike, with employers agreeing to sit down with both white and black union leaders. After 48 hours of negotiations, the employers agreed to the 10-hour day and overtime pay for the Triple Alliance workers. Members of other unions also won reduced hours and higher pay.


0

[L'appel du Blork] Racontez-nous vos aventures ludiques de la semaine ! 🎮🎲👾

preview

Mégafils de jlai.lu • Wiki de jlai.lu • Steam • Clavarder • UI alternative de jlai.lu

:::spoiler Navbox Fiction interactive • Jeux Plateau • Jeux Libres de RAOUL • Jeu de rôle • Jeux Vidéo • Linux Gaming


Arc Raiders • Dofus • Karmine Corp


Créer une équipe Coop • Discussion • Podcast • Ressources • 2024 • 2023 :::

:::spoiler Soutenir les jeux vidéo


Blork blork. Blork ! C’est dimanche jeu !

Vous montez une superbe config et vous avez besoin de conseil ? Blork !

Vous voulez monter une équipe ? Inscrivez-vous ! Blork !

Vous testez un jeu et vous avez envie de nous partager le fond votre pensée ?

Blork ! Votre affreux, Blork

Mégafils de jlai.lu • Wiki de jlai.lu • Steam • Clavarder • UI alternative de jlai.lu

:::spoiler Navbox Fiction interactive • Jeux Plateau • Jeux Libres de RAOUL • Jeu de rôle • Jeux Vidéo • Linux Gaming


Arc Raiders • Dofus • Karmine Corp


Créer une équipe Coop • Discussion • Podcast • Ressources • 2024 • 2023 :::

:::spoiler Soutenir les jeux vidéo


Blork blork. Blork ! C’est dimanche jeu !

Vous montez une superbe config et vous avez besoin de conseil ? Blork !

Vous voulez monter une équipe ? Inscrivez-vous ! Blork !

Vous testez un jeu et vous avez envie de nous partager le fond votre pensée ?

Blork ! Votre affreux, Blork