
whore rule

preview
No one writes this text with a straight face, right? Right?
setVeryLoud(true);
He / They
Software Developer
member since 19 Apr 2023 22:57
No one writes this text with a straight face, right? Right?

Article links to a biased source and there is no outside fact checking.
I suppose “Anthropic says” is accurate, but is it really newsworthy besides clicks and ad revenue to report on hearsay?
Biased source, bad article.
I use it for git commit signing.
Yeah isn’t that most music?
Oof :(
I’m not considering the 300 searches plan, I bust that basically instantly. The minimum plan I can use is the $10 USD, which is about $14 CAD.
I’m Canadian and their prices aren’t adjusted per market, so it’s pretty expensive for us. It’s about the price of YouTube Premium for a base plan. (I’ll go double check)
Edit: nope, YT Premium is a wild $27 CAD now, far from the $14 CAD for the cheapest unlimited search Kagi plan lol
I think we need more solutions like Kagi, but less expensive.
Since you’re the customer, no ads are served to you, and the search results are in your best interest and can be fully customized.
Looks like a 3D model to me. Happy to be proven wrong though.
I think it just means someone who shot at the sky with a bullet faster than earth’s escape velocity.
I have this as a sticker somewhere lol
24 is ideal, 16 works fine especially with some MoE offloading. If you use llama-swap, a fast PCIe bus and fast storage is ideal. Takes about 20 seconds to swap between two models on my X570 board.
Nah I got an RX 6800 XT for $300 with 16 GB VRAM, perfectly cromulent for a 27B model.
Maybe not a mobile device, but running decent local models is definitely within reach for the average consumer today by simply adding a GPU with lots of VRAM to their existing PC.
What do they invest in?
Good riddance. I love giving the middle finger to the empty warehouse with the shadow of an Amazon ensign when I drive past it.
I’m using PayloadCMS now. It’s fauxpensource, but eh, so is WordPress in a lot of areas.

omgwhere???
What is the difference between an Escher sentence and a non sequitur?
Care to elaborate?
Whichever one fits in my ass nicely
I never cracked the metal on any of my Lodge pans, and I regularly shock them from scalding hot to cold water. The steam seems to help release the residue quicker without ruining the seasoning.
For seasoning, I just coat it in canola oil upside down in the oven at 500 over a baking pan. Works fine.
I was gonna ask, “what kind of AI”
We really need to stop using the catch-all term AI, because it’s designed to let OpenAI and Anthropic take credit for everything ML and NN-related, and then even some.
24 GB VRAM. Damn, jealous! My 16 GB seems pitiful in comparison 😅
I do wonder if the Ryzen AI CPUs compare with Apple’s UMA. I’m mostly interested in LLM inference for code generation and automation.
You’re right, they’re not watertight. But I’m not trying to defend against MPI, just hallucinations. Never looked into Nix flakes, I always just used OCIs.
I actually did exactly that previously! I had both an RX 6800 XT and an RX 6600 in my system and I used the 6600 for video output. Unfortunately, this cuts my RX 6800 XT from PCIe 4 16x to PCIe 4 8x and severely slows down model loading for llama-swap. Joys of the X570!
And yes, I do have it running right now with a bit of occupied VRAM, but I need to limit my model to 14 GB to leave 2 GB free for GNOME Shell. I really want one of those 64 GB UMA Mac Mini, I heard they work really well because the GPU has direct access to system RAM.
Cheers, I’ll give this a try!
Regarding containerization, familiarize yourself with Dev Containers, they’re super useful for limiting agents to your codebase, with the added bonus that any project you work on comes out of the box with the right version of the tools you need.
It does!
Alarm: beeps
Push
Alarm: “I’m sorry Dave, I’m afraid I can’t do that”
…
Alarm: keeps beeping
No onboard graphics unfortunately, that would have been the easy way out.
How has tool use been for you? I struggled a lot with tool use with Gemma and Qwen, to the point where I needed to build a healing layer.
Regarding the coding harness, I was looking for something CLI-based or JetBrains-based, and I haven’t had much luck getting my local llama.cpp models playing ball with OpenCode. They keep losing context and misusing tools.
I’m not too familiar with Apple containers as I’m running a full Linux stack, but I’ll give Pi a try, seems interesting! Does it work for coding tasks or is it strictly an “orchestrator”?
Correct, that’s how I would do it, but then I need another machine to act as a head.
I meant your LLM stack lol. I just have an RX 6800 XT in my main Linux PC for inference, but it has to share VRAM with the DE. Maybe I’ll set it up for remote development from my laptop instead to free up VRAM.
What are you using? vLLM? llama.cpp? Which params? How much CPU offloading? Do you use draft models? Is it a MoE model? Have you tried llama-swap? Which agentic front-end are you using? I presume you set it up to access it without SSH’ing into the machine, did you do anything special or is it just a raw unsecured open port on the machine to the LAN?
connected smoke alarm
What the fuck? I would have simply bought a wall powered smoke alarm, opened it up, and wired an auxiliary button to the snooze button’s pads and put that button lower down as one of those wall switch buttons.
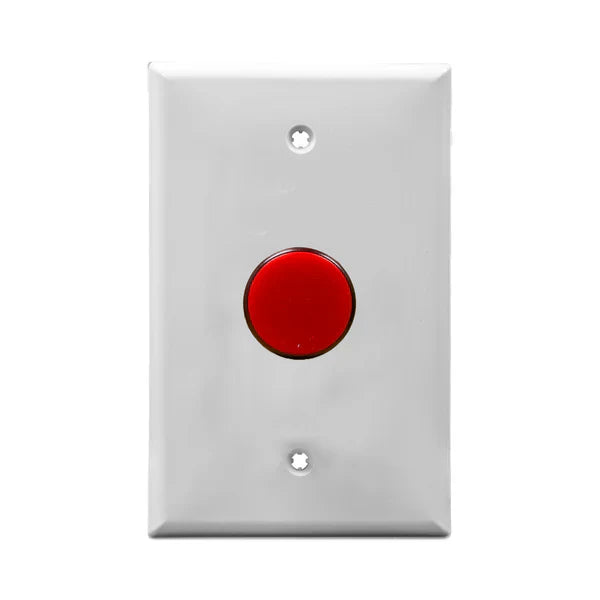
You really just need to complete the circuit to make it shut up.
Yeah? This has been a thing for years. We were training people at my previous place of work to ignore MFAs that did not originate from an action they took.
Gee, I sure hope nothing happens to that single location in Tennessee…
Show me your set up!
Don’t forget about “jerky”
They can be made without, and may be a perfectly cromulent option for shelf stable powder goods. The top and bottom are simply crimped rigid cardboard.
Moxie
Do they make glow in the dark hair dye?
Isn’t this just a twist on “degrees of Kevin Bacon”?
And r/beta
Complete with a moose knuckle
Why would they touch llama.cpp? It’s open source and has ROCm support.
I need to know what everyone has in their pants at all times with perfect accuracy! For… Reasons. Including, and especially, children! I must know what is in the pants of the children! For… Their own safety! Yes! Let kids be kids by making sure I know at all times what is in their pants!
I like my maps with GMOs
IMO regarding LED headlights, it mostly has to do with manufacturers putting LEDs in reflector housing.
Because of the way LED boards are, you can’t get a centric light. Standard LED boards are a cob, the best being those thin blades, but none of them are suitable for a pure reflector set up without pissing light everywhere.
LED head lights belong strictly in projector housings in order to have good cut off and spread. I drove an IONIQ 5 ultimate last year, and the head lights were shockingly bad. Not only did light piss everywhere, but it was downright dangerous in an urban setting as it would not illuminate the side walks nor the side of the road, so I could not see pedestrians waiting to cross at night.
I retrofitted the projector beam headlights in my 2020 Elantra with Diode Dynamics SL2 Pros, and after a height adjustment, they don’t blind anyone, nor bleed everywhere, have a great sharp-but-not-too-sharp cut off due to the mechanical shutter, and I can see the sides of the road clearly. They’re also not overly bright. I now have a 2026 K4 Hatchback, and the LED projectors are also great.
Meh, modern split headlight designs allow you to have a marketable front-end with headlights at the correct height.
Look at the Kona for example. The DRLs are way at the top yet the head lights are at the fender line. I think it looks good.
Bro, AI company logos make me so horny you don’t understand.