Star Detective Precure! The Movie: The Mysterious Garden and a Secret Pair - Key Visual (Updated)

What anime is basically this for you?

preview

For me, I think Infinite Stratos isn’t nearly as bad as people make it out to be. It’s not good, and I have my issues with it, but I’ve seen worse

The Quiet Decision Microsoft Made That Devastated Thousands of Nonprofits
slate.com
teto word of the day! Army
sh.itjust.workspreview
*posts like 5 Lemmy posts*
“oh that’s enough for right now I’ll just watch YouTube :)”
*first YouTube recommendation is an absolute banger of a meme*
Fairphone 6+ is now official and coming to the US
m.gsmarena.compreview
TLDR: it’s a spec bump for the processor and RAM. One question I personally had is does that mean the motherboard is backward compatible with the og FP6?
Trump 2.0 has deleted or altered nearly 400 US datasets, endangering public health, education and more
www.theguardian.compreview
cross-posted from: lemmy.world/post/50808662
Health data appears to be most affected by administration’s attempt to wipe findings that don’t align with its priorities, tracker shows
A database of federal law enforcement officer misconduct records. A survey measuring physical, sexual and emotional violence against children and youth. Real-time pollution readings collected by air quality monitors from US embassies around the world.
These are among the hundreds of federal datasets that the Trump administration has taken down or altered as part of its aggressive campaign to wipe all mentions of data findings that do not align with the administration’s priorities.
Over the past year and a half, at least 28 federal datasets have been deleted and another 338 data collections have been modified, according to an online tracker released last week from dataindex.us, a group of data policy experts, researchers and developers that formed last year to monitor changes to government data.
“We’re at a very vulnerable point as a nation,” said Denice Ross, former US chief data scientist under the Biden administration and a cofounder of dataindex.us. “We’re facing a future where we are not going to have the information that we need to make decisions that will save lives and benefit American communities.”

Need little help troubleshooting jellyfin
preview
Hello guys so I installed jellyfin on termux. It ran fine few hours ago. I turned it off and got running few times. Now when I’m trying to start jellyfin I’m getting this error
You must install .NET to run this application.
App: /data/data/com.termux/files/usr/lib/jellyfin/jellyfin
Architecture: arm64 App host version: 9.0.18
.NET location: Not found
Learn more:
https://aka.ms/dotnet/app-launch-failed
Download the .NET runtime:
https://aka.ms/dotnet-core-applaunch?missing_runtime=true&arch=arm64&rid=linux-bionic-arm64&os=linux-bionic&apphost_version=9.0.18
Failed to resolve libhostfxr.so [not found]. Error code: 0x80008083
Any suggestion to fix it ?
Meta Files Patent for Facial Recognition, Automatic Recording of People
www.privacyguides.orgpreview
‘Show How 3M Is 0% at Fault:’ Expert Witness Used ChatGPT to Write Report Defending Company in Deadly Explosion Lawsuit / ChatGPT prompts show how an expert witness report was created in a $61 millio…
www.404media.copreview
Full title: ‘Show How 3M Is 0% at Fault:’ Expert Witness Used ChatGPT to Write Report Defending Company in Deadly Explosion Lawsuit / ChatGPT prompts show how an expert witness report was created in a $61 million lawsuit over an explosion that killed three people.
GPU and RAM prices have both risen ~19% across the EU over the past 1-2 months, verified with fixed-basket price tracking
www.pricesquirrel.compreview
GPUs: +19.2% in one month

Fixed basket of 176 GPU models, tracked at 3+ retailers daily for 30 days (July 15 - August 14), to rule out the distortion that happens when cheap cards sell out and skew a simple daily average.
- July 15: €808.57 average
- August 14: €963.56 average +19.2%, same 176 cards throughout
Not a single spike, started climbing around July 24-25 and has been steady since. Consistent across markets too: Germany +19.6%, France +18.1%.
RAM: +18.6% over two months

Same fixed-basket approach: 112 DDR5 kits in stock at 2+ retailers on both June 19 and August 18, tracked daily throughout.
- June 19: €666.80 average
- August 18: €791.14 average +18.6%, same 112 kits throughout
This one had a sharper inflection point: flat through most of June, then a sudden +6% overnight jump on July 1 (checked individual SKUs to rule out a data glitch, it’s real, looks like a manufacturer-side price change hitting multiple retailers the same day), followed by continued climbing through mid-July, then a slower steady rise since.
Methodology, for both: price is the average across whichever 2-3+ retailers carried a given product on a given day, not the single cheapest price, and not a blended average across a shifting product list, a fixed set of SKUs, verified daily, same products at the start and end of the period.
Data limitation: RAM figures are consumer DDR5 desktop kits only
Independent corroboration: German tech outlet Heise recently reported a similar ~20% GPU price increase: heise.de/…/Grafikkarten-werden-nochmals-rund-20-P…
Data source: PriceSquirrel, tracking hardware prices across 20+ EU retailers.

Is Apple beginning a privacy reset?
www.computerworld.com
kitty

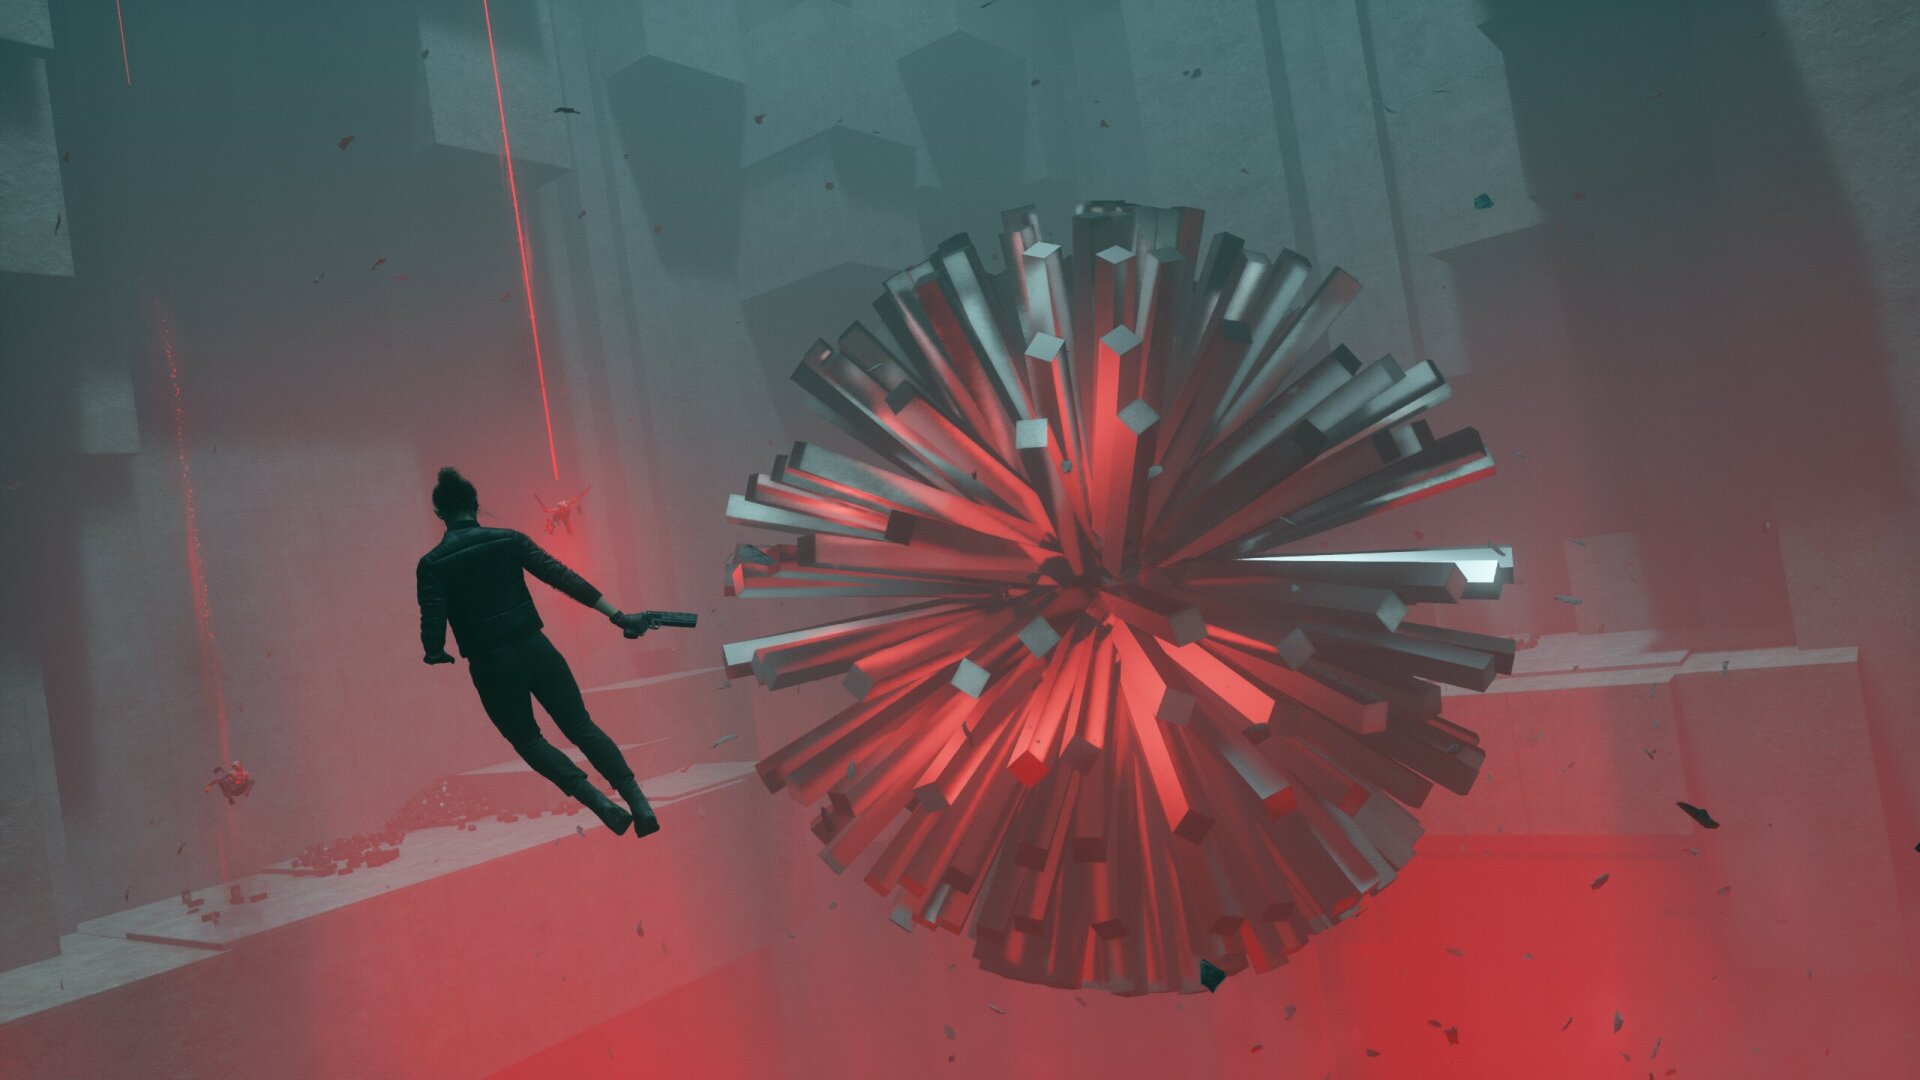
Day 762 of posting a Daily Screenshot from the games I've been playing
preview
Today’s game is Control. I went Anchor hunting today and did that whole questline. I can’t believe i had never done it up until that point. I would have expected me to easily have a run in with that location considering how accessible it is.
Nonetheless, I escorted the guy out. Then went back, found out i needed the levitate ability, progressed the story far enough to get it, then went all the way back to get it.
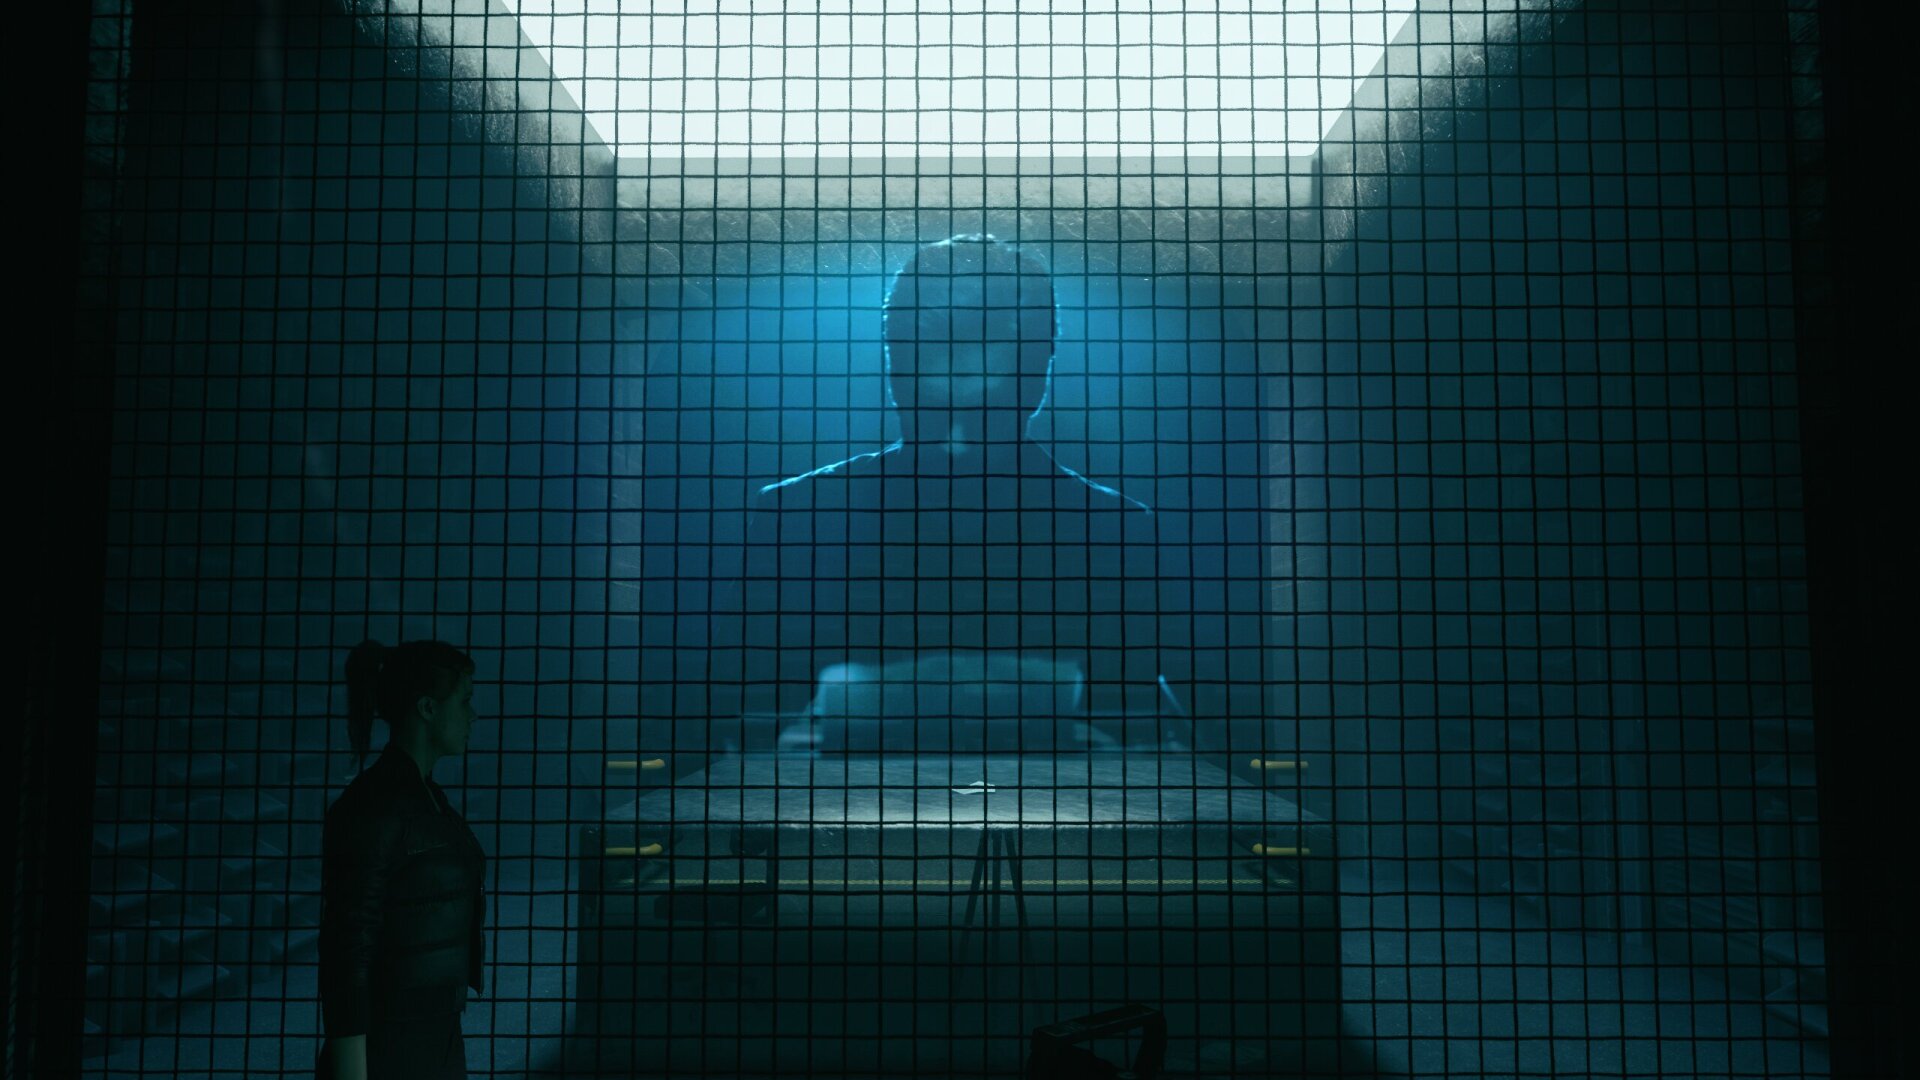
With this playthrough i’m not rushing through as much either. As such i’ve found so many references to Alan Wake that i just missed on my first playthrough. Such as this page with a narration by the man himself. There’s also a Coffee Thermos and a few pages describing people going through events similar to Alan’s Dreams.
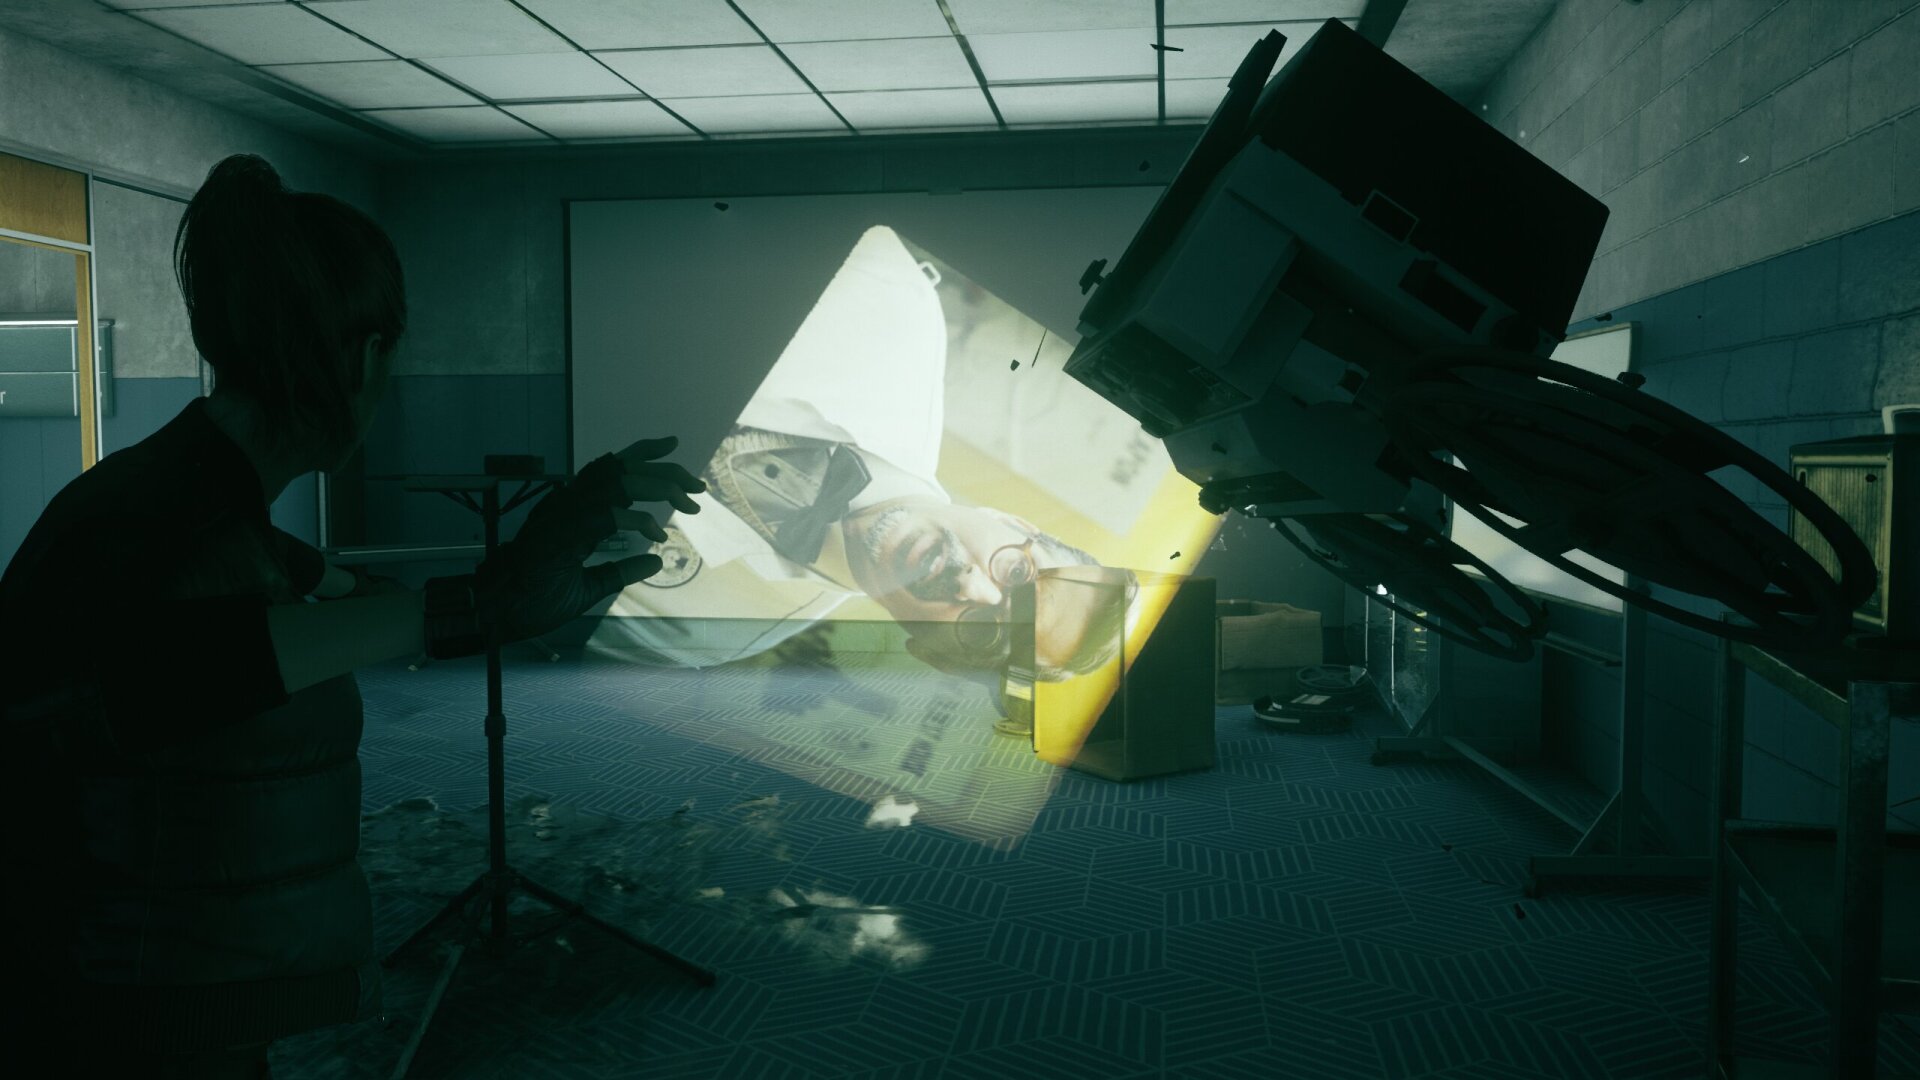
I also found out i can pick up the projectors. There’s nothing interesting about this, i just thought it was cool. I feel like a lot of games would just tie the projectors down rather than rendering a whole extra thing for rotating them and such. It was pretty cool.
I made my way through the whole Ordinary AWE site and i’m about to head over to the Research wing to mess with the projectors. This was about the point i remember last time getting too before the last “push” and finishing the main game. So i may very well finish it tomorrow and move back to the DLC.
Fingerprinting: The Hidden Trap on the Modern Web | MindDump
minddump-5f4.pages.devpreview
I wrote a blog post about fingerprinting.
And then the men with guns tell you to do it anyway – Terence Eden’s Blog
shkspr.mobiHow Bluesky draws its logo on screenshots
timmarinin.net
i'd lke to suggest a new word (transfem, surgeries)

preview
#image description
still of sam from lord of the ring. (the po-ta-toe scene) text:
“surgeon: penile inversion method me: per - ma - tuck”
More Renewables Lead To Lower Demand For Methane In Europe
cleantechnica.comYouTube will now count a view as soon as a video starts playing
techcrunch.com
‘Show How 3M Is 0% at Fault:’ Expert Witness Used ChatGPT to Write Report Defending Company in Deadly Explosion Lawsuit
www.404media.coI don't enjoy the Internet any more
btao.orgA solar powered website that goes offline when there's no power
solar.lowtechmagazine.compreview
This website made me reconsider if 99.9999% SLA and always online is really that important for lots of websites. I used to self-host my own server in my own apartment, but gave up on that after my internet provider had their first major outage that lasted almost a week. Also I didn’t want to worry about the fire hazard, or the server going down when I was traveling etc.
But a solar powered server seems interesting, if the batteries could be made fire safe.
A Megaman X fan game that was just released.
mmxregenesis.itch.iopreview
Someone just released a Megaman X fan game that mixes a lot of the mechanics of the series into a classic Megaman X package all done in Godot engine. Free over on itchio
What is your weirdest self-hosting problem you've had to solve? For me: Mouse inside the server.

preview
The mouse did not survive interrogation.
Also mouse not pictured.
I made a weird 2D action game where a catboy fights alien hordes — Starfish ROOM: WELCOME TO LOOP ETERNAL

preview

Hey everyone!
I’m SketBR, a solo indie developer, and I’ve been working on Starfish ROOM: WELCOME TO LOOP ETERNAL.
It’s a fast-paced 2D Musou/action roguelite where you play as Kibo Wave, a transgender catboy fighting hordes of monsters and aliens while trying to save mysterious ROOMS.

The basic loop is: Fight hordes → collect Core → complete objectives → choose random cards → survive the Flow → enter a Starfish Arena → fight an alien → repeat the loop.


There are also weird random cards, combo abilities, dash attacks, dynamite, alien bosses, and an eternal loop system where eventually you have to face Boki, Kibo’s clone from the future. I develop the game as a solo dev using GDevelop, and a lot of my development has been done directly on an Android phone. It’s definitely been a weird way to make a game, but I’ve learned a lot from it.

I’m posting this because I’d really like people to actually play it, rather than just look at screenshots. I’m especially interested in hearing whether the combat feels fun and whether the game keeps you interested after a few minutes.
Play it in your browser: kittycreampuff.itch.io/starfish-room-final
Steam page / wishlist: …steampowered.com/…/Starfish_ROOM_WELCOME_TO_LOOP…
Thanks for checking out my weird little game!
DEFEND THE ROOMS. BREAK THE CYCLE.
We Tracked a Shipment of Rare Books. It Ended at an Amazon AI Training Facility
www.404media.copreview
cross-posted from: lemmy.dbzer0.com/post/74144681
The symbol for Amazon’s VGT3, the Las Vegas facility where it scans book for AI training data.
Amazon is buying massive quantities of books, scanning them for AI training data, and destroying them in the process.
A 404 Media investigation was able to reveal Amazon’s book buying operation, which hasn’t been previously reported, by placing a tracking device in a rare book we suspected would be acquired by an AI company for training data, and following it around the country to its final destination.
That final destination was an Amazon warehouse in Las Vegas, Nevada. Amazon employees who work at this location say all they do is receive massive shipments of printed books which they then cut the bindings off in order to scan the books more quickly. The printed book is destroyed in the process. The logo of the Amazon team that works at this warehouse, called VGT3, is a dinosaur, brandishing its teeth and with a book in its hands.
“Amazon purchases books through commercial channels to help develop and improve the products and services our customers use,” an Amazon spokesperson told me in a statement.
The world’s AI companies are constantly looking for, and spending extreme resources to locate, more material to train their AI models. With books, that sometimes means destroying them in the process, something that large parts of the public have spoken up against, and which we can now confirm Amazon is doing.
In July, I published a story about booksellers who reported a historical spike in sales starting in the past year. They suspected this spike in sales was due to AI companies acquiring any books they can in search of new training data. Printed books are valuable as training data because a lot of the text they contain is not readily available on the internet, which AI companies have already scraped. The data is also conveniently organized and, if the book was printed before 2022, is guaranteed to be free of AI-generated text, which can make any AI model that is trained on it worse via a recursive process called “model collapse.”
📖 Do you know work at a facility where you scan books? I would love to hear from you. Using a non-work device, you can message me securely on Signal at @emanuel.404. Otherwise, send me an email at emanuel@404media.co.
These booksellers suspected AI companies were behind these large bulk purchases because of the high number of books they were buying, the seemingly random choice of books, and the fact that these buyers, unlike libraries and universities, did not seem price sensitive at all. But booksellers couldn’t say for certain who was behind the large purchases because the marketplaces where they sell their books keep the buyers anonymous. When an order comes in, a bookseller ships the sold books to a warehouse operated by the marketplaces, where books are sorted and then sent to the buyer.
In July, one bookseller told me they received a very large order of around 1,000 books on Biblio, one of these marketplaces. The seller agreed to put an Apple AirTag provided by 404 Media in one of the books included in this order so we could see where the book was going. And by extension, which company, AI or otherwise, was behind this massive order. 404 Media granted the bookseller anonymity because they worried sharing this information would harm their business. Biblio did not respond to a request for comment.
We Tracked a Shipment of Rare Books. It Ended at an Amazon AI Training Facility
www.404media.copreview
cross-posted from: lemmy.dbzer0.com/post/74144681
A 404 Media investigation was able to reveal Amazon’s book buying operation, which hasn’t been previously reported, by placing a tracking device in a rare book we suspected would be acquired by an AI company for training data, and following it around the country to its final destination. That final destination was an Amazon warehouse in Las Vegas, Nevada. Amazon employees who work at this location say all they do is receive massive shipments of printed books which they then cut the bindings off in order to scan the books more quickly. The printed book is destroyed in the process. The logo of the Amazon team that works at this warehouse, called VGT3, is a dinosaur, brandishing its teeth and with a book in its hands. “Amazon purchases books through commercial channels to help develop and improve the products and services our customers use,” an Amazon spokesperson told me in a statement. The world’s AI companies are constantly looking for, and spending extreme resources to locate, more material to train their AI models. With books, that sometimes means destroying them in the process, something that large parts of the public have spoken up against, and which we can now confirm Amazon is doing. In July, I published a story about booksellers who reported a historical spike in sales starting in the past year. They suspected this spike in sales was due to AI companies acquiring any books they can in search of new training data. Printed books are valuable as training data because a lot of the text they contain is not readily available on the internet, which AI companies have already scraped. The data is also conveniently organized and, if the book was printed before 2022, is guaranteed to be free of AI-generated text, which can make any AI model that is trained on it worse via a recursive process called “model collapse.” 📖 Do you know work at a facility where you scan books? I would love to hear from you. Using a non-work device, you can message me securely on Signal at @emanuel.404. Otherwise, send me an email at emanuel@404media.co. These booksellers suspected AI companies were behind these large bulk purchases because of the high number of books they were buying, the seemingly random choice of books, and the fact that these buyers, unlike libraries and universities, did not seem price sensitive at all. But booksellers couldn’t say for certain who was behind the large purchases because the marketplaces where they sell their books keep the buyers anonymous. When an order comes in, a bookseller ships the sold books to a warehouse operated by the marketplaces, where books are sorted and then sent to the buyer. In July, one bookseller told me they received a very large order of around 1,000 books on Biblio, one of these marketplaces. The seller agreed to put an Apple AirTag provided by 404 Media in one of the books included in this order so we could see where the book was going. And by extension, which company, AI or otherwise, was behind this massive order. 404 Media granted the bookseller anonymity because they worried sharing this information would harm their business. Biblio did not respond to a request for comment.
We Tracked a Shipment of Rare Books. It Ended at an Amazon AI Training Facility
www.404media.copreview
The symbol for Amazon’s VGT3, the Las Vegas facility where it scans book for AI training data.
Amazon is buying massive quantities of books, scanning them for AI training data, and destroying them in the process.
A 404 Media investigation was able to reveal Amazon’s book buying operation, which hasn’t been previously reported, by placing a tracking device in a rare book we suspected would be acquired by an AI company for training data, and following it around the country to its final destination.
That final destination was an Amazon warehouse in Las Vegas, Nevada. Amazon employees who work at this location say all they do is receive massive shipments of printed books which they then cut the bindings off in order to scan the books more quickly. The printed book is destroyed in the process. The logo of the Amazon team that works at this warehouse, called VGT3, is a dinosaur, brandishing its teeth and with a book in its hands.
“Amazon purchases books through commercial channels to help develop and improve the products and services our customers use,” an Amazon spokesperson told me in a statement.
The world’s AI companies are constantly looking for, and spending extreme resources to locate, more material to train their AI models. With books, that sometimes means destroying them in the process, something that large parts of the public have spoken up against, and which we can now confirm Amazon is doing.
In July, I published a story about booksellers who reported a historical spike in sales starting in the past year. They suspected this spike in sales was due to AI companies acquiring any books they can in search of new training data. Printed books are valuable as training data because a lot of the text they contain is not readily available on the internet, which AI companies have already scraped. The data is also conveniently organized and, if the book was printed before 2022, is guaranteed to be free of AI-generated text, which can make any AI model that is trained on it worse via a recursive process called “model collapse.”
📖 Do you know work at a facility where you scan books? I would love to hear from you. Using a non-work device, you can message me securely on Signal at @emanuel.404. Otherwise, send me an email at emanuel@404media.co.
These booksellers suspected AI companies were behind these large bulk purchases because of the high number of books they were buying, the seemingly random choice of books, and the fact that these buyers, unlike libraries and universities, did not seem price sensitive at all. But booksellers couldn’t say for certain who was behind the large purchases because the marketplaces where they sell their books keep the buyers anonymous. When an order comes in, a bookseller ships the sold books to a warehouse operated by the marketplaces, where books are sorted and then sent to the buyer.
In July, one bookseller told me they received a very large order of around 1,000 books on Biblio, one of these marketplaces. The seller agreed to put an Apple AirTag provided by 404 Media in one of the books included in this order so we could see where the book was going. And by extension, which company, AI or otherwise, was behind this massive order. 404 Media granted the bookseller anonymity because they worried sharing this information would harm their business. Biblio did not respond to a request for comment.
Another article to provide some clarity on the types of books: …biggo.com/…/37a2899b-5f1a-4571-9bb5-1156c0ac4605
it's both wild and awesome that people actually want to be so masc

OpenAI announces massive data center in Ohio with Nvidia guarantee
www.axios.comSelfhosting a printer (and scanner) server with UI
preview
I think it would be nice if my guests could easily print and scan when they are visiting.
Printing should be relatively easy nowadays with the printer on the same network. Scanning is another story. I found this nice project which works very nicely.
However, I would love to have the same but for printing, that way I would not have to do device specific troubleshooting/helping when trying to print something from guests’ devices.
There is this project, which has a screenshot of what seems to be exactly what I’m looking for, but the issues are unanswered, there is no release, the building of the project is lacking.
Dockerfiles are incomplete, they are lacking copy yarn.lock and api lacks db initialization. The ports seem to be hardcoded. And once built, it doesn’t work or at least I didn’t manage yet. I got the frontend finally up but can’t login. My knowledge is very limited so I’m checking with you if there is anything similar in the landscape or anyone willing to help on that project. Unfortunately I am locked out of github.
CUPS didn’t work for me as I can’t see an upload option on the web UI.
edit: So I spent time on tweaking the akronae repo, and after a few corrections, adding CUPS and improvements, I managed to get something functional. If I have more time I might publish it. It’s fully vibe coded though 'cause I couldn’t be arsed learning TypeScript and shit, and the original repo has plenty of outdated dependencies which, same, I won’t update because I don’t have the skills.
CME Group and Silicon Data to Launch Compute Futures on October 5 to Unlock New Way to Hedge AI Risks
www.cmegroup.compreview
cross-posted from: lemmy.dbzer0.com/post/74091518
CME Group, the world’s leading derivatives marketplace, and Silicon Data, the industry leader in GPU market intelligence and benchmarking backed by global trading firm DRW, today announced plans to launch two Compute futures contracts on October 5, 2026, pending regulatory review.
These innovative new trading tools will bring much-needed hedging and investment vehicles to businesses looking to manage the cost of compute, the processing power and hardware infrastructure that machines need to train and run AI models. Both Silicon Data H100 Rental Index Futures and Silicon Data B200 Rental Index Futures will track indexes measuring hourly rental GPU costs published by Silicon Data. Each contract will represent a month’s worth of rent for the Nvidia H100, the chip central to today’s AI ecosystem, and the next-generation Nvidia Blackwell B200, respectively.
“Compute has become the currency of the AI age, and this innovative market will bring transparency to the current and future costs that AI builders and hyperscalers need to hedge as they grow,” said Pete Keavey, Global Head of Energy and Environmental Products at CME Group. “Just as oil fueled the 20th century economy and evolved from spot trading into a global derivatives market, our futures contracts will now turn compute into a standardized, tradable commodity that will provide global businesses with a reliable, regulated venue to manage price risk .”
“For years, two companies buying the exact same GPU capacity could pay wildly different prices with no way to know who got the better deal. They will now have a benchmark to check that against,” said Carmen Li, Chief Executive Officer of Silicon Data. “Compute futures give the market something it’s never had: a public, tradable reference price for the resource every AI system runs on. Silicon Data’s benchmarks make that price real; CME makes it tradable. Together, that turns compute from something enterprises negotiate blindly into a market they can actually plan around.”
Explosive demand has driven sharp swings in compute prices, with volatility exposing a gap in the risk-management toolkit for companies building the AI infrastructure. CME Group and Silicon Data’s Compute futures close that gap, bringing transparency to the market and allowing companies, including AI developers and hyperscalers, to lock in their costs. They will also provide a window into future AI spending.
SAY IT
sh.itjust.worksApple is working on camera-equipped AirPods that appear to be nearly ready to launch, based on a video MacRumors found in the macOS Tahoe 26.7 release candidate.
www.macrumors.com
are price hikes of computers/consoles really due to ai?
preview
Mrwhoistheboss says that margin rose from 30 to 80% for memory companies and that the playstation price may increase from 400 to 1000. Does that really add up?
Unwinding the Great Tech Power Grab
rebeccawilliams.infopreview
Movements to reclaim power over technology are springing up, from Neo-Luddism to Permacomputing to Rewilding the Internet. Alongside these approaches, we must discuss how tech has atrophied the exact civic muscle we’ll need to reclaim power over it.
Last month, I had the pleasure of attending the Summer of Ludd, organized by NYC Off Tech and dedicated to getting people “off big tech, into public space, and re-enchanting each other.” Like the original Luddites rebelling against the machinery that stole their livelihoods, the Neo-Luddites are correct to rebel against today’s tech, which threatens our livelihoods, our privacy, our living world, our creative joy, and our ability to think.
Despite the heaviness of the stakes, the event itself was light: plays, puppets, clown workshops—I put on a gnome hat. My favorite moment of the event, which I dipped in and out of all week, was when a yellow gnome asked me to put my iPhone away and “carry this instead,” then passed me a hand-painted cardboard apple attached to a popsicle stick. How silly; how reasonable.
By itself, the event was not a labor movement; it was a cultural one. I think often about the divide between Abbie Hoffman and Tom Hayden as depicted in Aaron Sorkin’s The Trial of the Chicago 7. Abbie keeps insisting on the importance of cultural revolution through street demonstrations, theater, humor, and sexual liberation, while Tom dismisses it as a distraction from “actual revolution.” My favorite moment in the film comes when Abbie tells him, “We’re not going to jail because of what we did, we’re going to jail because of who we are. Think about that the next time you shrug off cultural revolution.”
I agree with Abbie: how people play, feel free, and come to see what’s possible matters just as much as formal politics. I also agree with Naomi Klein when she says surrealism expands our political imagination, and with David Graeber when he asks, What’s the Point If We Can’t Have Fun? My coalition is big enough for whimsy, and it can’t be effective without it.
‘I hate what AI is doing to the minds and happiness of the young’: Katherine Rundell on the view from the classroom
www.theguardian.comFacebook Is Drowning In Islamophobic AI Slop Calling for Violence Against Muslim Americans
futurism.comNew ChatGPT Feature Collects Every Keystroke You Make
futurism.comBefore you buy a game on GoG, see this growing list of 1,140 titles missing updates, DLC, and more....
www.windowscentral.com
GitHub you wiley fox!
moplemmy.fyiThe Naruto sexism Discourse we've had is directed at the wrong places.
preview

My problem is when people will read a book and say something like “why in a world with fantasy powers are men more likly to persue magic than women when their both equally capable of this must be proof that the author hates women”
I think a really good example is how naruto fans claim the author is sexist because most of the female ninja are weaker than the male ones and never “got” to persue their ninja job like the men". (note i do think the author of Naruto is sexist i just don’t agree with this reasoning.)
When, in the Naruto universe, men and women don’t have the same social norms as the real world. Not only are women in naruto from the clans are expected to and are forced to be ninja (essentially child soldiers) Most of early Naruto is literally both them the women and the men in the story lamenting the fact that being a ninja has stolen their lives away.
The women in Naruto going against the cultural norms of their society and actually freeing them selves from constant violence is not them conforming to patriacal standards especially not in universe its literally the exact oposite of that. It literally blows my mind that people make that point.
The sad thing about Sakara isn’t the fact that she never became as strong as Sasuke and Naruto. The sad thing about Sakura is the fact that even after multiple years to think on the problem she still thinks that she could have solved Sasuke’s emotional problems and trauma by punching him hard enough that he is forced to stay in the leaf. She never actually learned to communicate with other people outside of power and dominance and because of that is never truly able to empathize with either Naruto or Sasuke.
Also i just tend to look at fictional socities from a martrial realism point of view rather than a sociological
AI;DR (AI; Didn’t Read)
www.rickmanelius.comIt’s not drinking alone if your dog is home

preview
alt text
Manga girl sitting on the floor of the super market liquor aisle: When my parents ask when I’m getting married but this is the only aisle I’m walking down.
She got a lil spooked

Divine tech support

AI slop is eating the world. Trust is the first casualty
www.techradar.comCome back with new post :3
