36
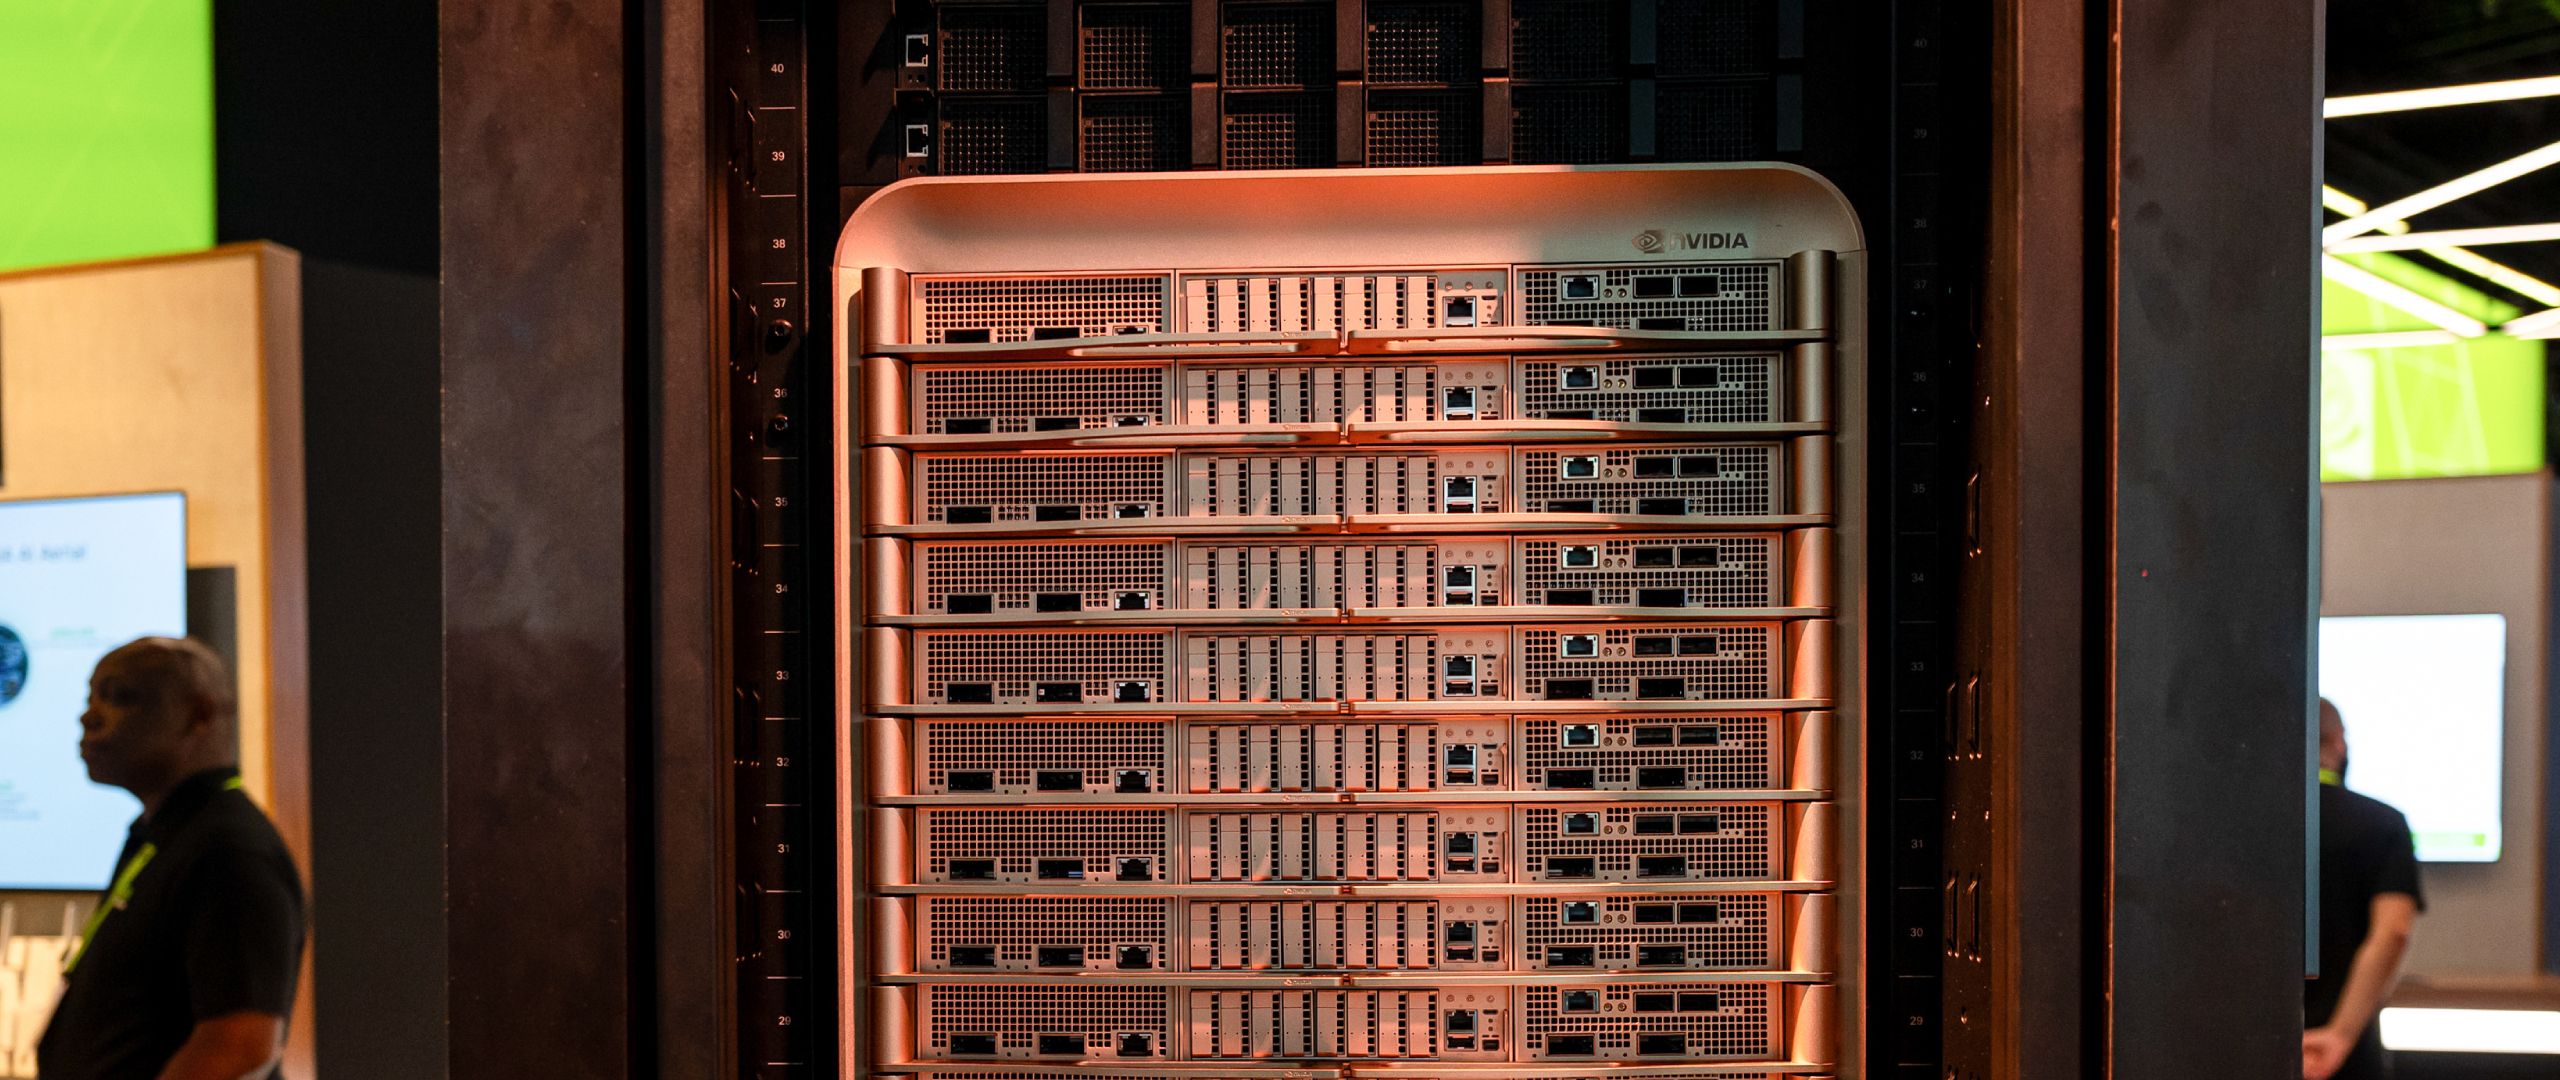
Software could be the easiest fix for hyperscalers' AI power squeeze, researchers say — data center demand is expected to rival Japan's electricity usage by 2030
Tom's Hardware
Software could be the easiest fix for hyperscalers' AI power squeeze, researchers say — data center demand is expected to rival Japan's electricity usage by 2030
Squeezing every ounce of performance per-watt
www.tomshardware.com
5 comments
log in to comment.
Thats kinda how the whole Chinese competition started - optimization to make due with limited hw.
Also I just changed the inference engine I use for local models and Qwen 3.8 27B went from 50tps to 150tps. The new engine is optimized for my hw.
What did you switch to?
Radiance. Was using the latest llama.cpp. This thread caught my eye as simple enough to try.
What are the specs of the machine that runs it?
2x R9700, Ryzen 7700, 64GB RAM. The absolute best I’ve seen from llama.cpp was 60tps but the typical was 45-55tps. Radiance gave me 150tps on the first try. It can do parallel output while keeping 80-120tps with 2-4 streams. It can do more in parallel but I heven’t tested what the numbers look like. As far as I understand these numbers are possible on a single R9700 with the MXFP4 model. Haven’t tried it.